The Hidden Cost of 'Locally Built' Agents: Compliance Risk, Key Person Dependency, and the Scale Problem
Originally published on corewrk.com.
A working AI agent on a developer’s laptop is not the same thing as a production AI system. The gap between the two is where compliance exposure, key person dependency, and scaling failure live. This post names the three hidden costs teams rarely account for until they are already paying them.
Product direction update — October 30, 2026: This dated article reflects earlier positioning. Helmfast now leads with governed setup for human and agent teams, with Build, Deploy, and Govern as the long-term platform direction. Earlier deployment scope and timelines are historical, not current release commitments. See the current platform direction.
The first time an AI agent works reliably, there is a tendency to treat the problem as solved. The agent runs, it produces the right output, and the team moves on. What they have actually done is create a working prototype that happens to be deployed in a production-adjacent environment.
The gap between “it works on my machine” and “it runs as a business system” is where three specific costs live. They are not obvious upfront, they tend to compound slowly, and by the time they become visible they are expensive to reverse. This post names each one and explains what teams can do about it.
Compliance risk: the credentials problem
A locally built agent almost always inherits its credentials from whoever built it. API keys live in a .env file, an environment variable, or a developer’s system keychain. The agent calls external services (an LLM provider, a CRM, a database, a third-party API) using credentials that are tied to a personal account or a shared key that was never provisioned for a production workload.
This creates a compliance exposure that surfaces in several ways. Personal API keys in a production agent mean that when the key rotates (or the person leaves), the agent breaks. A shared key with no access controls means there is no audit trail for what the agent called, when, or with what parameters. If the agent processes customer data or anything that falls under GDPR, HIPAA, or SOC 2 scope, the credential chain becomes a material compliance finding, not just a technical debt item.
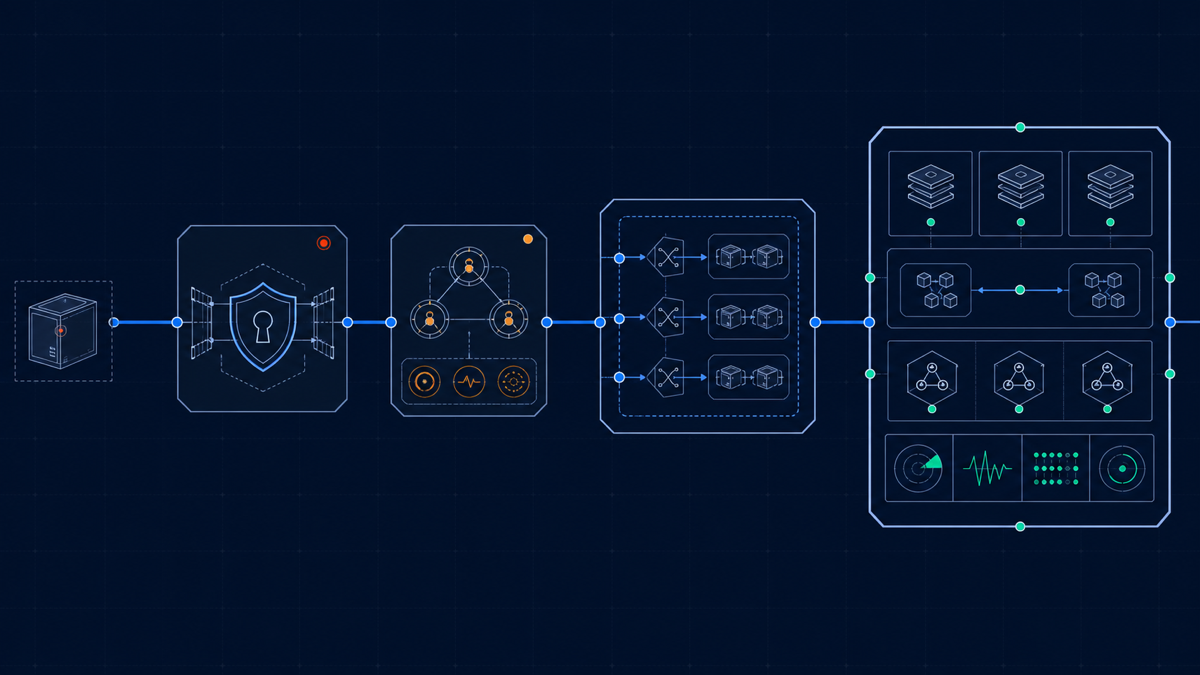
The fix is not complicated, but it requires intentionality: production agents need credentials that are provisioned for that agent specifically, rotatable independently of any person, and logged with enough granularity that an audit can reconstruct what the agent accessed. Most locally built agents do not have any of this, because no one explicitly designed for it.
Key person dependency: the single point of failure
There is usually one person who knows how a locally built agent actually works. They wrote the prompt chain. They understand why the output format is the way it is. They know which edge cases the agent handles gracefully and which ones cause it to fail silently. They know how to restart it when it stops running, and why it sometimes needs to be manually reset after a certain type of input.
This is key person dependency, and it is a structural risk that grows with every month the agent runs without being documented and operationalized. When that person is unavailable (vacation, illness, departure), the agent becomes a black box. The team can observe its outputs but cannot debug its behavior, cannot safely modify it, and cannot extend it for new requirements.
The pattern that prevents this is treating an AI agent the way you would treat any other production system: documented runbook, clear ownership, versioned configuration, observable behavior. None of that is complicated engineering, but it requires stepping back from “it works” and asking “can someone else operate this.”
The scale problem: one agent versus a system of agents
A single agent handling one workflow, running occasionally, on a developer’s machine is a fundamentally different thing from a set of agents handling multiple workflows, running on a schedule or trigger, at production volume.
The scale problem appears in several forms. An agent that works well when run manually may time out when run on a schedule against a larger dataset. An agent designed for one workflow may need to share a rate-limited API credential with two other agents, and the interaction between them is not something anyone thought through. An agent that produces correct output for ten records per day starts hallucinating for a different reason at a thousand records, and there is no observability layer to catch it.
Most locally built agents are designed for the case that was in front of the builder at the time. That is not a criticism—it is the correct way to start. The problem is when the organization treats “it works for this case” as equivalent to “it will work as the scope expands.” The expansion either requires a genuine systems architecture (which is real engineering work that should be planned for) or it requires a managed agent operations layer that handles the scaffolding so the team can focus on the logic.
What this means for teams building agents now
The three hidden costs are not arguments against building agents. They are arguments for being honest about what you have when you have a working prototype.
A locally built agent is a proof of concept, even when it is running in a production environment. Treating it as a permanent system without addressing the compliance layer, the key person dependency, and the scale question means the organization is carrying risks that are not visible on any dashboard.
The path forward is not to wait until you have a compliance team, an infra team, and a platform team. It is to make the transition deliberately: document what the agent does and how to operate it, provision proper credentials, and decide consciously what “scale” means for this specific workflow before the demand arrives rather than after.
For teams that want to move quickly without rebuilding the infrastructure scaffolding themselves, Helmfast is a managed agent operations layer—built specifically to handle the credential management, observability, and operational reliability that locally built agents typically lack. If your team has agents running in production and the three problems above sound familiar, start a conversation.